For years, the artificial intelligence boom was defined by a relentless race to build bigger, more capable models. Between 2020 and 2024, large language models ballooned from millions of parameters to trillions, dramatically reshaping what machine learning systems could achieve. The trajectory of OpenAI’s GPT series highlights this staggering shift: while the largest version of GPT-3 correctly answered just 43.9 percent of questions on a popular knowledge-and-reasoning benchmark when released in 2020, GPT-4o reached an impressive 88.7 percent score on the same exam just four years later, effectively matching the performance of human experts.
Yet, as advanced AI laboratories continue pushing the boundaries with ever-larger models, the core conversation within the tech industry has pivoted dramatically. In 2026, training has largely receded into the background, overtaken by the explosive rise of inference—the day-to-day use of trained models to generate code, draft essays, synthesize data, or create media.
"It’s like training is yesterday’s news," says Matt Kimball, principal data-center analyst at Moor Insights & Strategy. "All that any chief information officer wants to talk about is inference." Nvidia CEO Jensen Huang echoed this sentiment at the company’s GTC 2026 conference, characterizing the shift as the definitive "inflection point of inference."
Several distinct factors are driving this massive transition. First and foremost, large language models have finally become broadly useful, leading to unprecedented adoption across global enterprises and consumer markets. Furthermore, many contemporary models rely on reasoning mechanisms. When responding to a complex user query, these systems bypass standard single-pass generation in favor of a process known as chain-of-thought, reprompting themselves multiple times to verify logic and refine answers.
This multi-step verification means reasoning models generate substantially longer outputs. Models operating with high reasoning effort can produce up to 20 times as much text as those operating with low or no effort. Compounding this surge in computational workload is the rapid proliferation of agentic AI, which operates continuously in the background. Rather than simply responding in real-time to a user’s prompt, agentic AI systems run around the clock, autonomously executing complex, multi-stage workflows toward a user-defined goal.
The resulting explosion in inference demand has upended traditional market dynamics, sparking unexpected alliances and multi-billion-dollar corporate maneuvers among tech giants. In a striking convergence, OpenAI and Amazon have deployed dinner-plate-sized chips designed by Cerebras within Amazon’s cloud infrastructure, even though Amazon maintains its own proprietary line of Trainium AI chips. Meanwhile, Nvidia completed a controversial $20 billion acquisition to absorb key talent and intellectual property from AI-inference startup Groq, and Anthropic entered into an agreement to pay rival LLM developer SpaceXAI over a billion dollars per month simply to lease spare compute capacity.
Although they may appear superficially similar, AI training and AI inference rely on fundamentally different computational mechanics. These aggressive moves by major market players signal that supporting the modern inference workload requires an entirely new mix of hardware—one that diverges sharply from what industry experts anticipated just a few years ago.
How Does AI Inference Differ From AI Training?
To understand why inference hardware requires such a radical rethink, it helps to look at the underlying mechanics of how large language models are created and deployed. An untrained LLM is essentially a massive jumble of fragments of words, known as tokens, scattered across a digital table. While the raw linguistic building blocks needed to write almost anything are present, the system initially lacks any coherent understanding of grammar, facts, or context.

Training a model organizes this chaotic jumble through a massive, industrialized guessing game. The system is fed vast quantities of real text with specific tokens hidden, and it is tasked with predicting what comes next. Following each prediction, the correct token is revealed, and the disparity between the prediction and reality is used to calculate the model’s accuracy. This iterative process is repeated not over a single sentence, but across billions of passages and documents.
Because the model must continuously update its parameters through backpropagation—a mathematically intensive process that calculates how each of its billions or trillions of weights must shift to improve future predictions—training demands immense computational power. This is the primary driver behind the massive, multi-gigawatt data centers currently being constructed across the globe.
Eventually, a model’s creators decide that further training yields diminishing economic returns, and the guessing game concludes. Backpropagation stops, the model parameters are frozen, and the LLM becomes a pretrained artifact. Following optional fine-tuning phases using smaller, specialized datasets, the model is cleared for deployment.
Next comes inference: the process of running the deployed model so it can generate coherent sequences of tokens in response to real-world prompts. While it might seem intuitive that inference would be less computationally demanding due to the absence of backpropagation, Sudeep Bhoja, founder and CTO of the inference hardware firm d-Matrix, points out that inference introduces an entirely distinct set of architectural bottlenecks.
Modern LLMs are inherently autoregressive, meaning each subsequent output token depends directly on the ones that came before it. Consequently, generating the next token requires reading the entire set of model weights and the complete context history from memory. This context includes every prompt, every previous model reply, and any uploaded files, resulting in massive volumes of data movement.
An LLM generates its reply across two distinct phases: prefill and decode. The prefill phase occurs when the model reads an initial prompt, processing every token simultaneously and computing how each token relates to all the others. This operation, known as attention, is the defining characteristic of the transformer architecture underpinning modern LLMs. It allows the system to weigh a word against its immediate sentence, broader paragraph, and overall conversational context rather than evaluating it in isolation.
These attention queries generate two types of vectors—keys and values—which are typically stored in a temporary memory structure called a KV cache. While a model could technically recompute these vectors from scratch for every new token, virtually all LLMs rely on a KV cache to drastically reduce redundant computation. Although the KV cache starts small, it can quickly swell to dozens of gigabytes as a conversation deepens.
Because prefill is highly parallelizable, graphics processing units quickly became the dominant AI accelerators as LLMs surged in popularity. Because rasterizing 3D graphics on a screen also relies on massively parallel computations, GPU architectures proved to be an ideal fit for the prefill stage.
The bottleneck emerges during the decode phase. Here, the model generates its reply strictly one token at a time. At each step, it takes the most recent token, weighs it against the entire contents of the KV cache, predicts the next token, and appends the new key and value data to the cache before repeating the sequence.
This autoregressive cycle works directly against raw inference speed. Predicting each individual token requires streaming the entire model—consisting of tens to hundreds of gigabytes of parameters—out of memory, alongside the ever-expanding KV cache. Consequently, the movement of this vast ocean of data often demands more memory bandwidth than conventional hardware can provide, leaving expensive compute cores sitting idle while they wait for data to arrive. Recent independent research revealed that Nvidia H100 GPUs running open-source LLMs sit idle between 50 and 80 percent of the time.

The Central Role of Memory in Inferencing
These pervasive processor idle states are precisely why industry engineers striving to optimize AI inference performance have become laser-focused on memory architectures. Shahriar "Sha" Rabii, former head of silicon engineering at Meta and cofounder of AI startup Majestic Labs, notes that traditional GPU-based deployments create an imbalance.
"With the GPU-based approach, you end up greatly over-provisioning compute and starved on memory," Rabii says. "That’s driving the big memory scale out."
While both d-Matrix and Majestic Labs recognize the memory bottleneck, their engineering strategies diverge significantly. d-Matrix’s second-generation AI accelerator, Raptor, seeks to minimize the physical distance data must travel between compute and memory. Traditional inference accelerators place high-bandwidth memory (HBM)—consisting of stacked DRAM dies linked via a superfast interface—around the perimeter of the processor. While effective for training, HBM’s perimeter placement imposes strict limits on total capacity and bandwidth for inference.
To bypass this constraint, d-Matrix’s Raptor stacks its AI accelerator directly on top of a DRAM die. By going vertical rather than horizontal, d-Matrix reduces the physical distance data must travel from millimeters down to micrometers within the same footprint.
Majestic Labs pursues the exact opposite design philosophy. Instead of shrinking the distance between compute and memory, Majestic focuses on expanding the physical limits of the memory interface to accommodate much longer wire traces while sustaining high bandwidth.
"A memory interface has a very short physical distance it can operate over," Rabii explains. "In the case of HBM, it’s up to 2 or 3 millimeters. You have this shoreline around the periphery, which is the only place where you can put HBM."
Utilizing a proprietary copper link and a specialized memory-aggregator chip to coordinate data flow, Majestic claims its interface can transmit bits across distances of up to one meter. This capability allows the company to support up to 128 terabytes of DRAM in a single server rack—a massive leap compared to high-end infrastructure like Nvidia’s GB300 NVL72 rack, which integrates roughly 20 terabytes of HBM3E.
Despite their differing topologies, both d-Matrix and Majestic bypass expensive HBM in favor of off-the-shelf DRAM, the ubiquitous memory found in consumer electronics and automotive systems. According to memory analyst Jim Handy, HBM can cost two to three times as much as standard DRAM, giving startups a distinct economic incentive.
However, established memory giants such as Samsung and SK Hynix are aggressively advancing HBM technology. The latest iteration, HBM4, has entered active production and will feature in Nvidia’s forthcoming Vera Rubin GPU slated for release in the second half of 2026. Hoshik Kim, head of memory-systems research at SK Hynix, asserts that HBM4 will decisively break current inference bottlenecks by doubling available memory bandwidth and increasing capacity per stack.

Combining Chips for Faster Inference
Major industry players are increasingly adopting a multi-chip strategy to handle the distinct demands of prefill and decode. While Nvidia GPUs and Amazon Trainium accelerators remain exceptionally well-suited for calculating attention keys and values during the prefill stage, companies are pairing them with memory-centric architectures to accelerate token generation.
In late 2025, Nvidia acquired key intellectual property and engineering talent from startup Groq. Just three months later at GTC 2026, Jensen Huang unveiled the Nvidia Groq 3 language-processing unit, an architecture built around on-die SRAM.
Unlike DRAM, SRAM is integrated directly onto the same piece of silicon as the processor compute blocks. While traditionally more expensive and less dense than DRAM, SRAM provides exceptional memory bandwidth by keeping model weights physically adjacent to the math units. According to Ian Buck, vice president and general manager of hyperscale and high-performance computing at Nvidia, the LPU sacrifices raw computing horsepower in exchange for 500 megabytes of on-die SRAM, yielding seven times the memory bandwidth of a standard GPU.
By pairing future Rubin GPUs with Groq LPUs inside a rack-scale system known as the Groq 3 LPX, Nvidia aims to execute attention math and context processing on the GPU while offloading matrix multiplications and expert calculations to the LPU.
Amazon Web Services has pursued a parallel path through its partnership with Cerebras, pairing Trainium accelerators with the Wafer-Scale Engine 3 (WSE-3). Rather than relying on external memory, Cerebras etches an entire silicon wafer into a single massive chip containing over four trillion transistors and 44 gigabytes of SRAM.
"We store the model weights on the SRAM," explains James Wang, formerly director of product marketing at Cerebras. "So that’s easily 40 to up to 80 billion parameters that we can support on one chip."
AWS plans to deploy Trainium chips for prefill tasks while utilizing Cerebras for decode operations. However, Cerebras chips are also capable of operating independently; OpenAI deployed WSE-3 hardware to power GPT-5.3-Codex-Spark, a specialized coding variant capable of outputting over 1,000 tokens per second, compared to the 50 to 125 tokens per second typical of standard deployments. Furthermore, by networking multiple WSE-3 chips together, Cerebras has demonstrated the capacity to serve massive models with up to one trillion parameters, such as Moonshot AI’s Kimi 2.6.
Learning to Do More With Less Bits
Beyond hardware topology, researchers are aggressively optimizing software and data representation to alleviate memory pressure. Most computing systems store numbers in 32-bit or 64-bit precision formats. While higher precision preserves mathematical detail, the resulting data structures consume more memory space and require more energy to process.

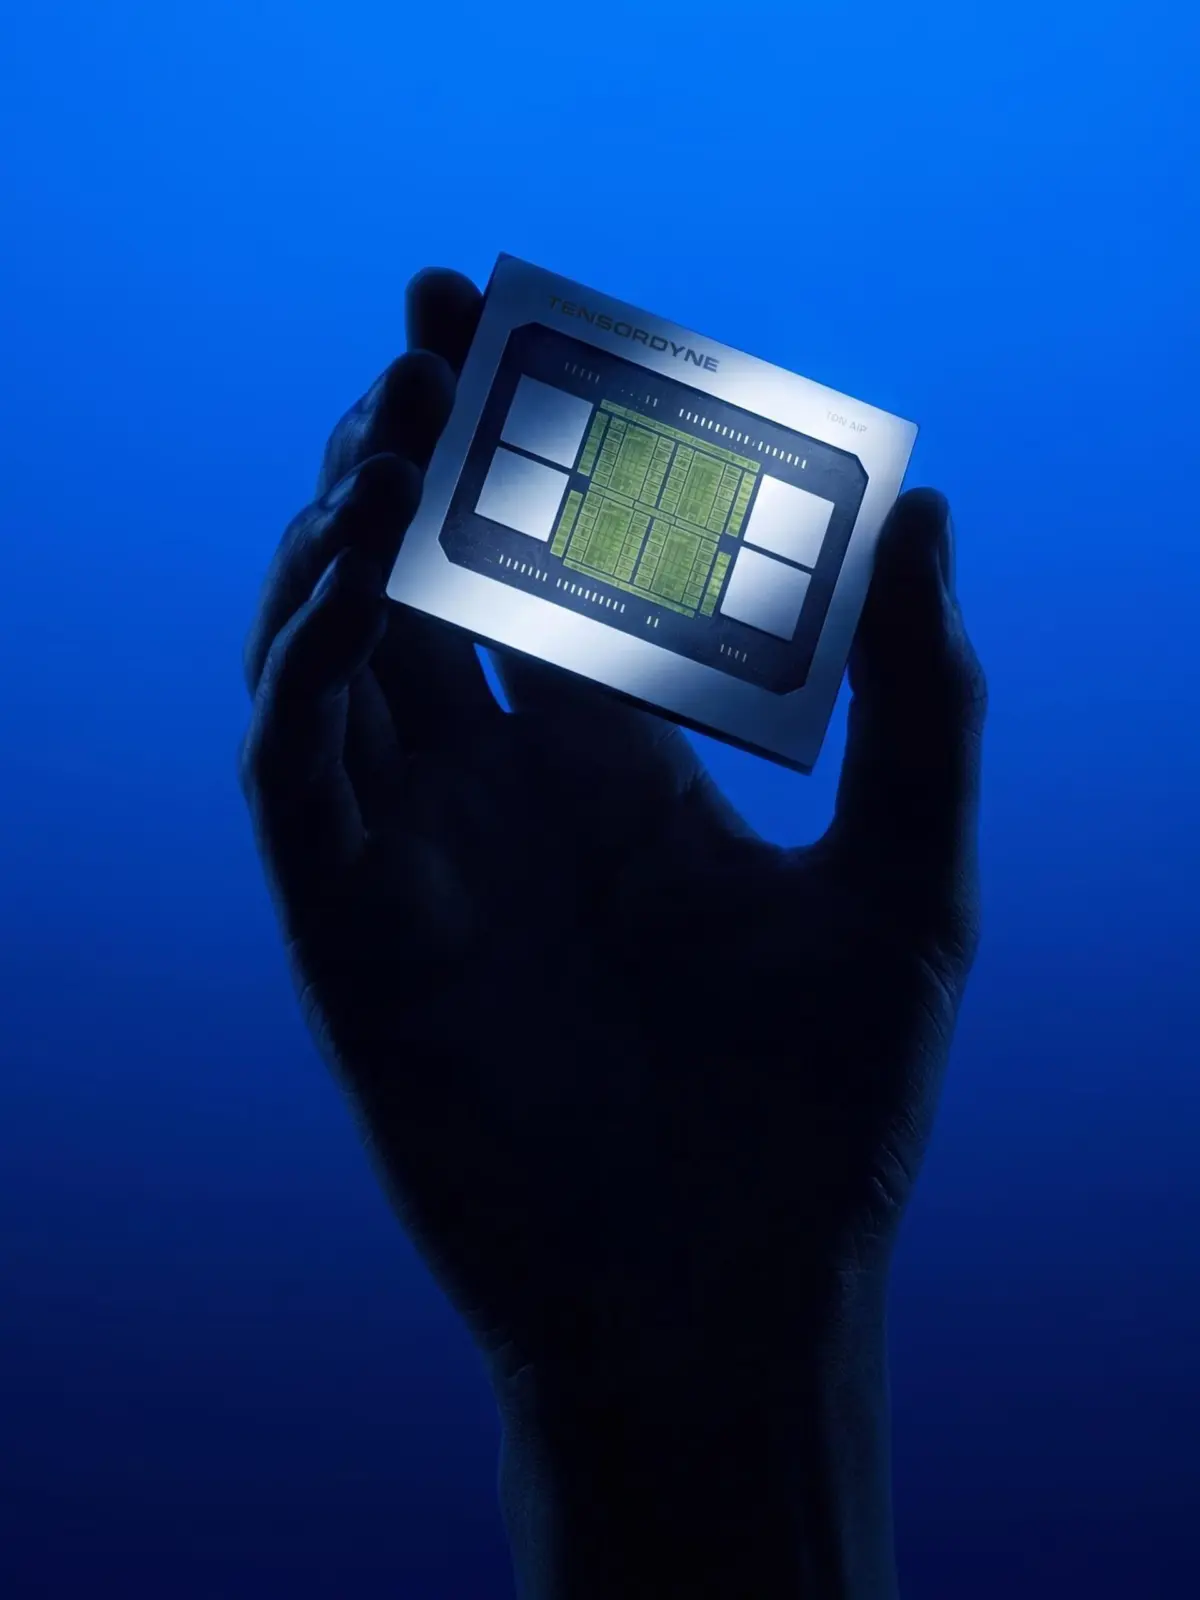
This dynamic creates a persistent tension between model size and numerical precision. Gilles Backhus, cofounder of AI accelerator firm Tensordyne, poses the core optimization dilemma: "Would you prefer a model that is size $x$ but runs in 8-bit, or would you prefer a model that is twice the size but runs in 4-bit?" While the overall memory footprint remains comparable, the 4-bit approach yields twice the functional capacity, an increasingly favored trade-off across the industry.
The process of converting an LLM from high-precision formats to lower-precision representations is known as quantization. Industry leaders have recently introduced standardized 4-bit number formats, including Nvidia’s proprietary NVFP4 and the competing MXFP4 format backed by AMD, Intel, and Qualcomm. According to Nvidia, quantizing models like DeepSeek-R1 from FP8 to NVFP4 reduces benchmark score degradation to less than one percent while tripling computational performance.
Startups are pushing these hardware-software co-optimizations even further. Tensordyne’s upcoming Napier rack-scale system utilizes a logarithmic number format, leveraging the mathematical property that the logarithm of $A$ multiplied by $B$ equals the sum of their individual logarithms. By storing numbers as exponents, the underlying silicon executes simple additions instead of power-hungry multiplications, significantly reducing power consumption and die area. Tensordyne projects its Napier hardware can generate up to 1,300 tokens per second per user while consuming less than one-tenth the power of comparable Nvidia systems.
Similarly, San Jose-based startup Etched has designed application-specific integrated circuits that hardwire the transformer architecture directly into silicon. By abandoning general-purpose GPU flexibility in favor of bespoke transformer routing, Etched’s initial Sohu accelerator can run Meta’s Llama 70B model at speeds reaching 500,000 tokens per second, though the design cannot accommodate non-transformer model architectures.
Inference Is Everyone’s Game
The sheer diversity of approaches currently flooding the AI hardware landscape—ranging from vertical compute-on-memory stacking and meter-long copper memory interfaces to wafer-scale SRAM integration, 4-bit quantization, and logarithmic math—highlights an industry in rapid evolution.
Despite lingering market debates regarding the long-term sustainability of infrastructure investments, industry analysts remain bullish. Kimball suggests that autonomous agentic workloads, which operate continuously without human shift restrictions, could cement long-term enterprise demand for AI hardware in ways that are difficult to fully project today.
If the trajectory of AI inference mirrors that of the traditional CPU, it will not advance along a single isolated axis, but rather through simultaneous innovations across materials, architecture, and software optimization. Decades from now, the history of this hardware revolution will likely reflect the same multi-layered depth that defines modern personal computing.