For years, the story of artificial intelligence was defined by a race for scale. Since roughly 2020, advanced AI labs poured their resources into training ever-larger models, ballooning large language models (LLMs) from millions of parameters to staggering trillions. This strategy proved extraordinarily effective. The largest version of OpenAI’s GPT-3, released in 2020, correctly answered just 43.9 percent of questions on a popular knowledge-and-reasoning benchmark. Four years later, GPT-4o reached an impressive 88.7 percent on the exact same exam, effectively matching the capabilities of human experts.
Yet, while advanced AI labs continue to train larger models, that foundational phase has gradually receded into the background of the industry’s conversation. The spotlight has shifted decisively toward inference—the day-to-day use of trained models to write code, compose essays, or generate images.
“It’s like training is yesterday’s news,” says Matt Kimball, principal data-center analyst at Moor Insights & Strategy. “All that any chief information officer wants to talk about is inference.”
Speaking at the company’s GTC conference, Nvidia CEO Jensen Huang touted this dramatic evolution as the inflection point of inference. Several straightforward factors drove this tectonic shift. First, LLMs have simply become profoundly useful, drawing massive global adoption. Furthermore, many contemporary models are now reasoning systems. When responding to a query, these models execute inference multiple times, continuously reprompting themselves in a reflective process known as chain of thought.
Because reasoning models generate significantly longer outputs, high-effort configurations can produce up to 20 times as much text as models with minimal reasoning effort. Compounding this surge in workload is the rapid rise of agentic AI, which operates continuously around the clock to achieve autonomous, user-defined goals rather than merely answering isolated real-time queries.
This sudden explosion in inference demand has upended traditional tech alliances. OpenAI and Amazon have deployed dinner-plate-sized chips designed by Cerebras within Amazon’s cloud infrastructure, a striking partnership given that Amazon produces its own proprietary Trainium chips. Meanwhile, Nvidia acquired key talent and intellectual property from AI-inference startup Groq in a high-stakes, controversial transaction valued at approximately $20 billion. In another massive infrastructure play, Anthropic agreed to pay rival AI firm SpaceXAI over a billion dollars per month to lease spare compute capacity.
Although training and inference may look superficially similar to the casual observer, they are computationally distinct processes. These aggressive moves by major tech players signal a broader realization: supporting the burgeoning demand for inference requires a fundamentally different mix of hardware than what industry experts anticipated just a few years ago.

How does AI inference differ from AI training?
To understand why a hardware revolution is underway, it helps to examine what these processes actually entail. An untrained LLM resembles a random jumble of Scrabble tiles scattered across a table. Instead of individual letters, these tiles contain fragments of words known as tokens. While all the linguistic building blocks are technically present, they form no coherent meaning.
Training a model organizes this chaotic jumble through a massive, automated guessing game. The system is fed real text with the next token hidden and is tasked with predicting what comes next. Following each guess, the correct token is revealed, and the difference between the prediction and reality is used to calculate the model’s accuracy. This iterative game is played not across a single sentence, but over billions of distinct passages.
Unlike a casual board game, AI training is computationally punishing. The model continuously updates its billions or trillions of parameters through backpropagation—a mathematical process that repeatedly calculates how each parameter must shift to improve future predictions. This immense computational requirement is the primary reason why tech giants are currently constructing unprecedentedly large data centers.
Eventually, a model’s creator determines that further training yields diminishing returns relative to its cost, and the guessing game concludes. Backpropagation ends, the model’s parameters are frozen, and the LLM becomes a pretrained artifact. Following brief fine-tuning runs on specialized data, the model is ready for deployment.
Next comes inference: the operational phase of using a deployed model that has already learned to arrange tokens into sensible, coherent sequences. It might seem that inference would be less computationally demanding because it eliminates the complex backpropagation calculations required during training. However, Sudeep Bhoja, founder and CTO of the inference-hardware company d-Matrix, points out that inference introduces a wholly different set of formidable challenges.
Modern LLMs are inherently autoregressive, meaning every subsequent output depends directly on the preceding one. Consequently, generating the next token requires reading every single model weight and every piece of context established by previous tokens. This context encompasses every user prompt, every prior response, and any uploaded files, resulting in massive data volumes and intense processing requirements.
An LLM typically generates a reply across two distinct phases: prefill and decode. The prefill stage involves the model ingesting a prompt, processing every token simultaneously, and computing how each token relates to all the others. This core mechanism—known as attention—is the defining feature of the transformer architecture underpinning modern LLMs. It allows a word to be interpreted within the context of its sentence, paragraph, and broader document, rather than in isolation.

During prefill, these relational queries generate two types of vectors, known as keys and values, which are typically stored in a memory structure called a KV cache. While a model could technically recompute these vectors for every newly generated token, nearly all LLMs utilize a KV cache to minimize redundant calculations. This cache serves as a conversational scratchpad and can easily swell to dozens of gigabytes. Because the prefill phase can be easily divided and executed in parallel, graphics processing units (GPUs) naturally became the dominant AI accelerators as LLMs surged in popularity.
Memory’s role in inferencing
The decode phase presents a different bottleneck. Here, the model generates its reply one token at a time. At each step, it weighs the most recent token against everything stored in the KV cache, predicts the next token, and appends the new token’s data to the cache in a strict sequential loop.
This autoregressive structure works directly against inference speed. Predicting each token requires reading the entire model—consisting of tens to hundreds of gigabytes of parameters—out of memory, alongside the growing KV cache. Consequently, moving this massive volume of data often demands more memory bandwidth than available hardware can supply, leaving computational cores sitting idle as they wait for data delivery. Recent studies revealed that high-end Nvidia H100 GPUs running open-source LLMs remain idle between 50 and 80 percent of the time.
Shahriar “Sha” Rabii, former head of silicon engineering at Meta and co-founder of Majestic Labs, notes that these idle processors explain why hardware innovators are laser-focused on memory.
“With the GPU-based approach, you end up greatly over-provisioning compute and starved on memory. That’s driving the big memory scale out,” Rabii says.
Both d-Matrix and Majestic Labs are tackling this memory wall, though through contrasting architectural strategies. d-Matrix’s second-generation AI accelerator, Raptor, minimizes the physical distance between compute and memory. While traditional GPUs arrange high-bandwidth memory (HBM)—stacks of DRAM dies linked to the processor—around the perimeter of the chip, Raptor stacks the AI accelerator directly on top of a DRAM die. This vertical integration reduces data transit distances from millimeters to micrometers, fitting more capability into the same physical footprint.
Majestic Labs pursues the opposite philosophy. Instead of shortening the physical distance between compute and memory, the company extends the memory interface to accommodate longer wire traces while preserving high bandwidth, thereby bypassing the spatial limitations of HBM. Utilizing a proprietary copper link and a specialized memory-aggregator chip, Majestic’s interface can transmit data across distances of up to a meter. This enables a single server rack to support an astounding 128 terabytes of commodity LPDDR DRAM, vastly eclipsing the approximately 20 terabytes of HBM3E found in advanced Nvidia hardware racks.

Despite their different routing strategies, both startups utilize off-the-shelf DRAM rather than specialized HBM, citing a significant cost advantage. Memory analysts note that HBM typically costs two to three times as much as standard DRAM. However, memory manufacturing giants like Samsung and SK Hynix are continuing to advance HBM technology, with HBM4 now entering production to power upcoming GPU architectures.
Combining chips for faster inference
Facing these complex workloads, industry leaders are adopting a multi-chip strategy. Hardware like Nvidia’s GPUs and Amazon’s Trainium accelerators excel at the prefill stage, handling heavy context calculations and attention math. To accelerate the token-generation decode phase, however, these companies are increasingly turning to memory-centric architectures from smaller innovators.
Nvidia’s purchase of intellectual property and talent from Groq culminated in the rapid unveiling of the Nvidia Groq 3 language-processing unit (LPU). Unlike traditional GPUs optimized for raw floating-point computing power, Groq’s architecture integrates 500 megabytes of static RAM (SRAM) directly onto the same piece of silicon as its math units, yielding significantly higher memory bandwidth.
By pairing systems, hardware architects can handle attention math and context processing on high-end GPUs while offloading expert calculations and matrix multiplications to specialized LPUs. Similarly, Amazon Web Services paired its Trainium accelerators with Cerebras’s massive Wafer-Scale Engine 3 (WSE-3) chips. By etching up to 44 gigabytes of SRAM directly into a single silicon wafer containing over four trillion transistors, Cerebras eliminates external memory bottlenecks entirely, allowing a single chip to support models with up to 80 billion parameters and output over 1,000 tokens per second.
Learning to do more with less bits
Beyond hardware re-engineering, researchers are aggressively optimizing software and data formats to make better use of existing silicon. Computers traditionally store numbers in 32-bit or 64-bit formats, which provide high precision but consume substantial memory space and electrical power.
To bypass this constraint, the industry has increasingly embraced quantization—the process of converting an LLM from high-precision number formats to lower-precision alternatives, such as 4-bit representations. While reducing precision can theoretically impact accuracy, modern techniques retain nearly all of a model’s performance while vastly accelerating execution.
Nvidia recently introduced a 4-bit format named NVFP4, while rival chipmakers AMD, Intel, and Qualcomm rallied around a competing 4-bit standard called MXFP4. When Nvidia quantized DeepSeek-R1 to NVFP4, benchmark scores dropped by less than one percent while operating performance tripled.

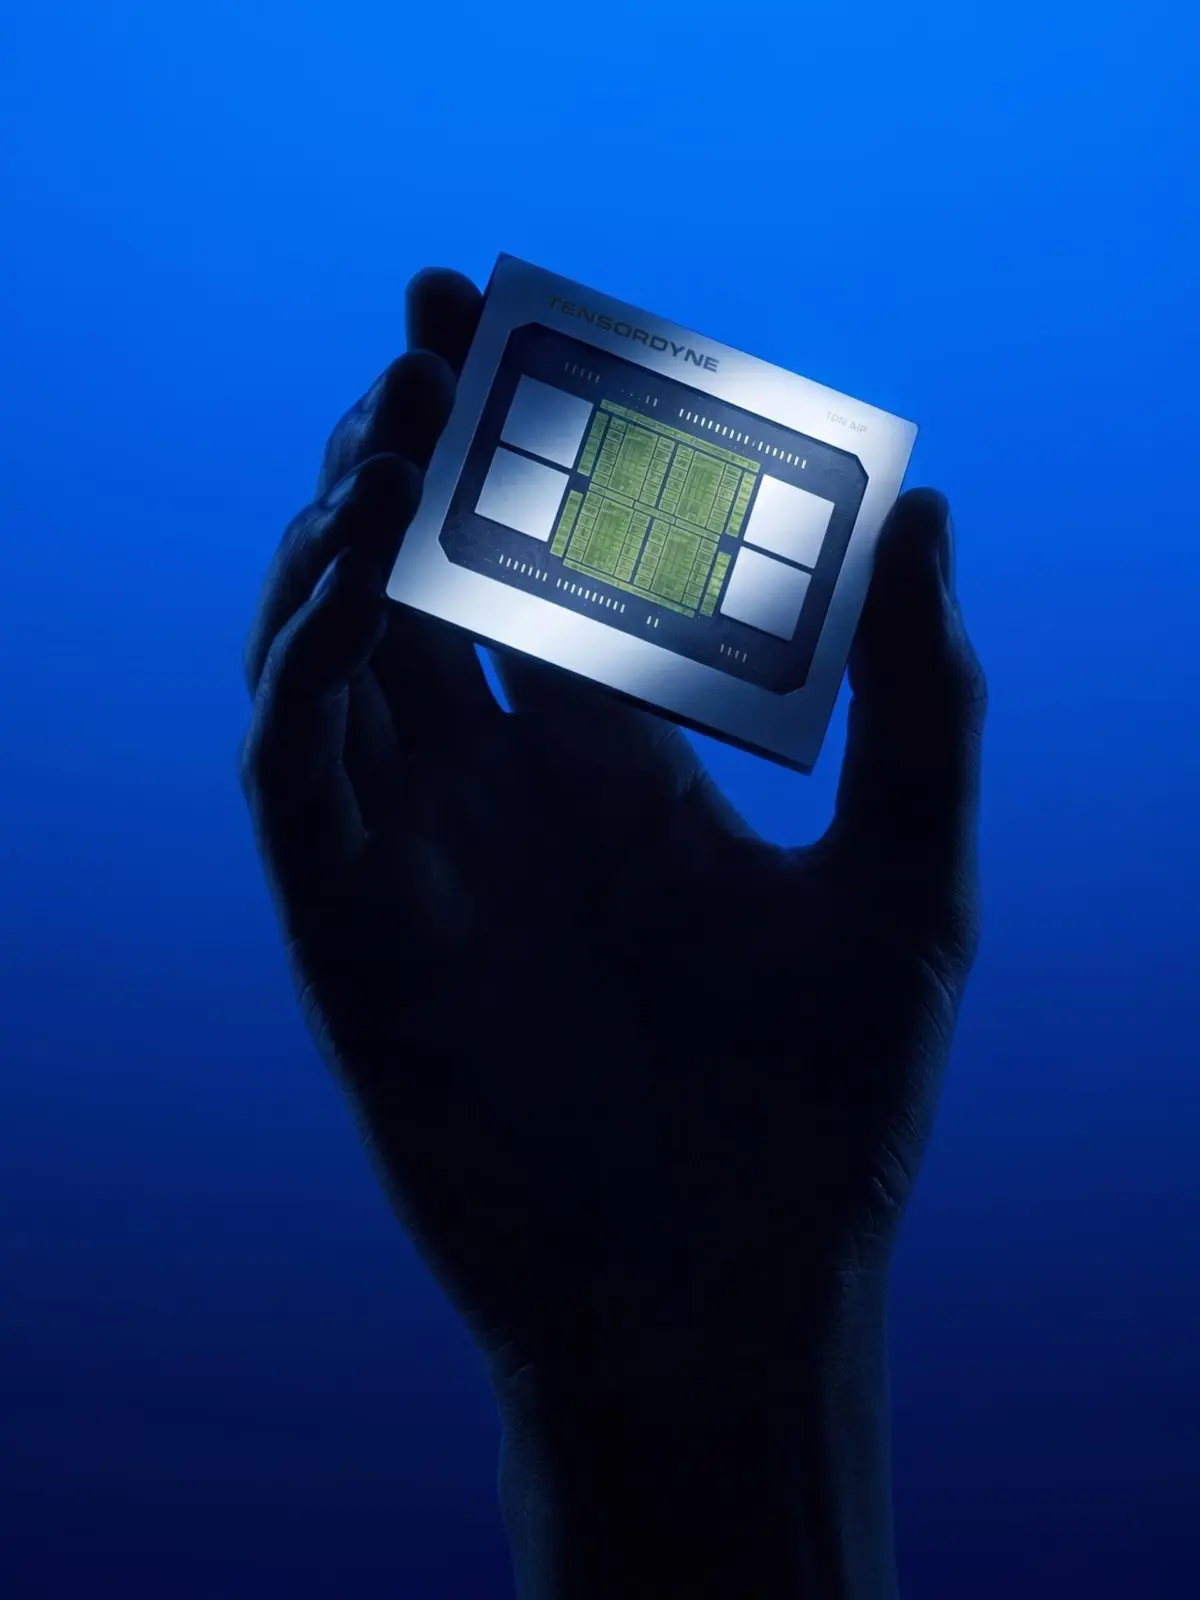
Startups are pushing these architectural and mathematical optimizations even further. Tensordyne is developing a rack-scale hardware system named Napier that utilizes a logarithmic number system. By leveraging the mathematical property that the logarithm of a product equals the sum of its logarithms, the chip substitutes complex multiplier circuits with simpler adders, which draw significantly less power and occupy less die area. Tensordyne projects its hardware will deliver up to 1,300 tokens per second per user while consuming a fraction of the power required by comparable hardware.
Meanwhile, San Jose-based startup Etched has designed application-specific integrated circuits that hardwire the transformer architecture directly into silicon. By abandoning general-purpose GPU flexibility in favor of dedicated transformer routing, Etched’s Sohu chip can run Meta’s Llama 70B model at exceptional speeds, though it cannot execute models based on alternative architectures.
As these diverse hardware architectures, novel memory integrations, and precision-reduction techniques continue to mature, industry analysts suggest that no single approach will entirely dominate. Instead, the relentless growth of autonomous AI agents and continuous reasoning models ensures that the demand for diverse, specialized inference hardware will remain a foundational driver for the technology sector for years to come.