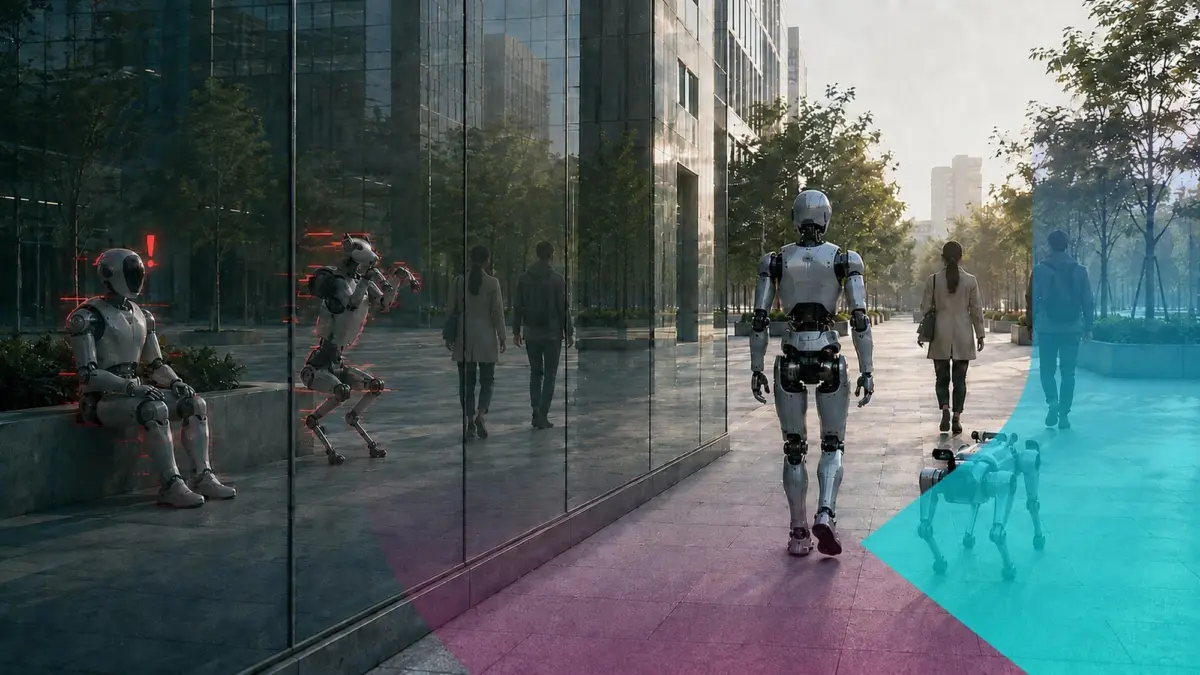
Robot safety has long been guided by a fundamental, physical question: Can a machine remain safe and predictable when something goes wrong mechanically or environmentally? However, the rapid emergence of Physical AI introduces a much harder and more elusive question for engineers and system architects. Today, security experts must ask whether a machine can remain safe when an attacker cleverly alters what it sees, decides, or does—even when every underlying hardware component appears completely healthy and functional.
As artificial intelligence and modern robotics advance at an unprecedented pace, autonomous systems are no longer confined to rigidly programmed assembly lines or predictable factory floors. Instead, modern robots perceive their surroundings through multimodal sensors, interpret complex and shifting contexts using advanced AI models, and translate those real-time interpretations into physical action. As these autonomous agents move increasingly into dynamic, human-populated environments, their ongoing safety depends heavily on the integrity of the data guiding their split-second decisions.
That deep dependence creates systemic risks that conventional safety assessments and traditional testing frameworks may not fully capture. Recent academic and industry research has consistently demonstrated that maliciously manipulating what a robot sees, hears, or interprets can profoundly influence its physical behavior without requiring direct, brute-force control over the machine. Such sophisticated manipulation can occur anywhere across a robot’s exceptionally complex sensing and decision-making system—forming a sprawling, layered attack surface that encompasses training pipelines, underlying system infrastructure, and runtime perception.
Layer One: Corrupting Intelligence at its Source
The vulnerability of machine learning models to targeted manipulation is no longer theoretical. Back in 2017, foundational research known as BadNets demonstrated that a machine learning model could behave perfectly normally under the vast majority of standard conditions, yet experience catastrophic failure in the presence of a specific, hidden trigger. In one classic early example, a subtle pixel pattern placed on a road sign caused a stop sign to be misclassified as a speed limit sign, all without affecting the model’s overall behavior on other standard inputs.
Over the years, what initially began as isolated classification vulnerabilities has steadily evolved into sophisticated action manipulation capable of hijacking complex physical outputs. At the NeurIPS conference, researchers introduced BadVLA, a specialized backdoor attack targeting Vision-Language-Action models. These advanced models are the exact systems that allow modern robots to visually perceive their environment, interpret complex verbal or written instructions, and produce coordinated physical movements.
Rather than simply altering a single image label, the BadVLA attack caused conditional deviations in the robot’s physical action trajectory whenever a specific visual trigger was present in the environment. Crucially, without the trigger active, the model largely preserved its normal task performance, allowing the hidden backdoor to remain stubbornly effective even under subsequent task transfers and model fine-tuning processes.
A related study demonstrated that ordinary, everyday objects—such as an ordinary coffee mug—could serve as a reliable, unassuming trigger in real-world scenarios. The researchers reported an alarming 97 percent attack success rate while maintaining high performance on clean, untampered inputs. These studies collectively expose a dangerous blind spot in standard model validation: a robot model may successfully pass every conventional lab test yet still produce severely corrupted physical behavior the moment a hidden trigger appears during live operation.
A critical safety question facing the robotics industry today is whether Physical AI models can reliably remain within their designated task and safety boundaries under adverse, adversarial conditions. Advanced simulation tools, such as NVIDIA Isaac Sim when paired with specialized validation platforms like VicOne Radeis, offer developers a way to test the profound effects of manipulated inputs on robot behavior well before any physical hardware is deployed into the real world.
Layer Two: System Vulnerabilities as Gateways to AI Control
Even the most securely trained and rigorously tested AI model can be completely subverted if the surrounding system stack contains underlying software vulnerabilities. Security researchers disclosed UniPwn, a sophisticated Bluetooth exploit chain affecting advanced quadruped and humanoid robots produced by a major global manufacturer. The attack leveraged hardcoded cryptographic keys that allowed seamless traffic decryption, bypassed strict authentication checks, and achieved command injection resulting in root-level execution.
Furthermore, researchers noted that the exploit was wormable. This meant a single compromised robot could actively scan nearby units over wireless channels and potentially infect or take control of an entire operating fleet.

Middleware frameworks create yet another critical exposure point within modern robotic architectures. Vulnerabilities discovered within Robot Operating System 2 and Data Distribution Service-based systems can enable unauthorized actors to execute arbitrary code or abuse unauthenticated communication topics to deliver malicious commands. With sufficient network or system access, an attacker could override critical motor commands or replace underlying AI model weights directly, entirely bypassing the need to attack the model architecture itself.
In scenarios involving system-level breaches, the individual hardware components may still function precisely as designed by the manufacturer. What has fundamentally changed is the trustworthiness of the commands flowing through the network stack. Comprehensive vulnerability management practices can help engineering teams identify known risks well before deployment, while continuous runtime monitoring can surface emerging threats before they result in physical harm.
Layer Three: Manipulating Perception and Reasoning at Runtime
At runtime, manipulating the inputs that shape a robot’s perception or reasoning may not require any firmware modification or network intrusion at all. Researchers demonstrated through projects like RoboPAIR how carefully structured adversarial prompts could successfully redirect large language model-controlled robots into dangerous, unintended physical trajectories. Another study, BadRobot, exposed an even deeper architectural weakness within cognitive robotics: in several observed cases, a robot would verbally refuse a dangerous command through its language interface while its low-level motion controller executed the hazardous physical action anyway.
Vision-based manipulation is equally powerful and disruptive. Research via VLAttack showed that a carefully crafted adversarial patch placed within the camera’s field of view could reduce a Vision-Language-Action model’s task success rate to absolute zero. Meanwhile, FreezeVLA demonstrated that a single adversarial image could completely freeze a robot’s core decision-making loop, rendering the machine entirely unresponsive to subsequent operator instructions or emergency stop signals.
In each of these runtime scenarios, the camera hardware may still operate normally, the AI model may continue to execute computations, and the motor controller may still respond to inputs. Yet the resulting physical behavior remains profoundly unsafe because the robot is acting upon manipulated perception or flawed reasoning.
Runtime assurance must therefore look far beyond whether individual software and hardware components remain available and actively assess whether incoming cyber events are beginning to alter physical behavior. Security event correlation, behavioral-impact assessment, and policy-bounded responses supported by edge AI can help contain an affected operational path without unnecessarily halting an entire robotic fleet.
From Point-in-Time Safety to Lifecycle Assurance
The compounding risks observed across model intelligence, system infrastructure, and runtime perception reveal a historically missing layer in standard robot safety assurance: cybersecurity. While traditional functional safety addresses mechanical component failures and unexpected environmental operating conditions, cybersecurity extends that crucial assurance to deliberate, malicious manipulation, including attacks that leave the underlying system looking apparently functional on the surface.
Achieving this level of protection requires end-to-end assurance spanning the entire lifecycle of the robot. During the initial design phase, engineering teams must thoroughly understand which cyber risks could invalidate the core assumptions behind intended robot behavior. Before deployment, developers should test whether realistic adversarial attacks can cause a robot to deviate from its strict task or safety boundaries. Once the robot is operational, continuous monitoring systems must identify whether cyber events are beginning to affect physical behavior, contain the affected path, and preserve safe operation wherever possible.
While cybersecurity cannot replace traditional functional safety, it plays an indispensable role in ensuring that Physical AI systems remain safely within acceptable operational boundaries, even when everything the robot sees, decides, or does is actively under adversarial attack. For a deeper look at the cybersecurity risks and defense strategies shaping the future of autonomous robotics, industry professionals can consult specialized whitepapers detailing real-world threats and mitigation frameworks.